We will answer the questions:
-
What exactly is ‘normality’
-
What is the purpose of testing for normality?
-
How do we test for normality?
-
graphical method
-
statistical method
-
-
Multiple ‘equivalent’ statistical tests: which do I use?
-
Are there errors in the logical foundations of normality testing?
What exactly is ‘normality’?
Statistical tests are broken into to broad categories: ‘parametric’ and ‘non-parametric’.
Parametric refers to statistical tests that take advantage of making specific assumptions that the data are drawn from a normal, or Gaussian distribution.
Non-parametric is usually only defined in relation to parametric tests in the sense that they relax at least one of the assumptions of the Gaussian distribution. Non-parametric statistical tests make weaker assumptions regarding the true distribution of the data, such as that the distribution is symmetrical, or that it is singly-peaked.
Parametric tests are more powerful than non-parametric tests, in the sense that you can find a statistically significant result with fewer gaussian datapoints with a parametric test (that assumes the data are normally distributed) than with an equivalent non-parametric test (that does not assume the data are normally distributed).
Normality, when referring to data, is just the property of having been drawn from a Gaussian distribution.
What is the purpose of testing for normality?
-
When performing any statistical test, you must be aware of the assumptions that go into that test. Statistical tests are, technically, only valid when the assumptions of the test are met.
- Normality tests are tests to determine whether data are normally distributed, and therefore whether we can validly use parametric statistical tests.
-
Let’s take a look at some data drawn from a few distributions, and decide if it is obvious whether or not each was drawn from a normal (Gaussian) distribution:
MATLAB
d=randraw(‘Cauchy’,[20 1.1],[20 1])
d(:,2)=randraw('Poisson',[50],[20 1])
d(:,3)=randraw('Normal',[25 3],[20 1]);
d(:,4)=randraw('t',[30 25 3],[20 1]);
d(:,5)=randraw('vonmises',[1 .2],[20 1]);
d(:,6)=randraw('nakagami',[5 5],[20 1]);
Python
import numpy as np
from scipy import stats

rng = np.random.default_rng(1)
size = 20
# Distribution parameters are explicit rather than hidden in randraw.
# Cauchy: location=20, scale=1.1; Normal: mean=25, sd=3.
# Student t: df=30, location=25, scale=3.
# von Mises: mean direction=1 radian, concentration=.2.
# Nakagami: shape m=5, spread omega=5; SciPy scale=sqrt(omega).
d = np.column_stack([
    stats.cauchy.rvs(loc=20, scale=1.1, size=size, random_state=rng),
    rng.poisson(50, size),
    rng.normal(25, 3, size),
    25 + 3 * rng.standard_t(30, size),
    rng.vonmises(1, .2, size),
    stats.nakagami.rvs(5, scale=np.sqrt(5), size=size, random_state=rng),
])
names = ['Cauchy', 'Poisson', 'Normal', 'Student t', 'von Mises', 'Nakagami']
which can be plotted with the commands:
MATLAB
figure;
for n=1:6,
subplot(3,2,n); hold on;
a=histogram(d(:,n),9); r=axis;
sd=std(d(:,n)); m=mean(d(:,n));
r=[min([r(1) m-3*sd]) max([r(2) m+3*sd]), 0 max([1.1*a.Values r(4)])];
axis(r); t=linspace(r(1),r(2),301);
nG=normpdf(t,m,sd);
plot(t,1.02*max(a.Values)*nG/max(nG),'k--'); end
Python
import numpy as np
from scipy import stats
import matplotlib.pyplot as plt

# Uses d and names from the data-generation block above.
fig, axes = plt.subplots(3, 2, figsize=(8, 9))
for column, ax, name in zip(d.T, axes.flat, names):
    counts, edges, _ = ax.hist(column, bins=9, color=(.55, .62, .73), edgecolor='.3')
    mean, sd = column.mean(), column.std(ddof=1)
    lo, hi = min(edges[0], mean - 3 * sd), max(edges[-1], mean + 3 * sd)
    t = np.linspace(lo, hi, 301)
    normal = stats.norm.pdf(t, mean, sd)
    ax.plot(t, 1.02 * counts.max() * normal / normal.max(), 'k--')
    ax.set(xlim=(lo, hi), ylim=(0, 1.1 * counts.max()), title=name)
fig.tight_layout()
plt.show()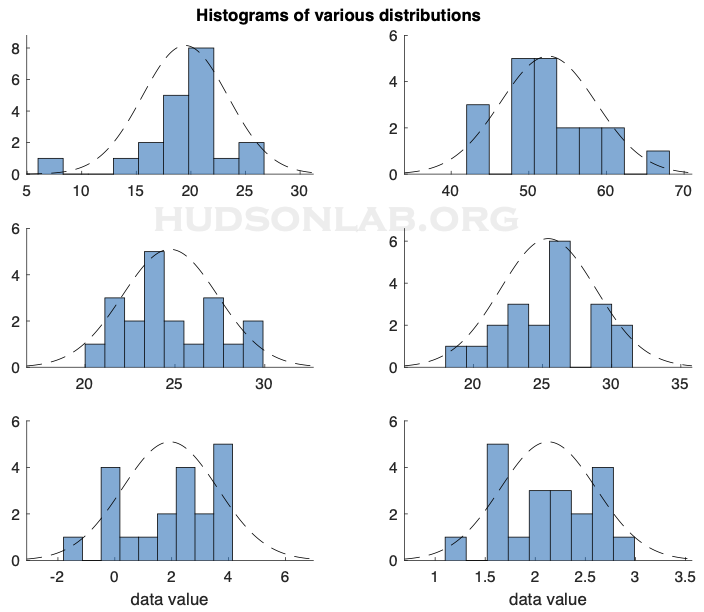
Notice that in these figures we have also plotted a Gaussian probability distribution over the top of each histogram.
Which of these histograms look like they were drawn from a normal distribution?
The answer is that only the middle left histogram was drawn from a normal distribution, but several other histograms nevertheless seem to conform just as well to the overlaid normal density function.
The fact that it is very difficult, at least without a great deal of data (histograms of thousands of datapoints are usually much easier to recognize as normal vs. non-normal), has led to the widespread use of statistical normality testing.
How do we test for normality?
Normality can be tested in two general ways: qualitatively using a graphical method, or statistically. We will demonstrate both.
1) graphical method
-
The graphical method in widest use is the q-q plot
- this stands for ‘quantile-quantile’.
-
The basic idea of the q-q method is to plot the data from your experiment against what would be expected if your data were actually normally distributed.
-
This type of plot, in which actual data and predicted data are plotted against one another, is always predicted to fall along a straight line.
- In actual practice, there are some subtleties because you do not know the mean and standard deviation of the distribution from which your data are sampled, and you therefore plot your data against the predictions of the ‘standard’ normal distribution; the normal distribution with mean 0 and standard deviation 1.
-
Finally, note that the predictions are in terms of the quantiles of the data and the quantiles of the standard normal; what percentage of the data are above or below the mean, or above/below one standard deviation from the mean, etc.
- A q-q plot can be made using the code:
MATLAB
figure
for n=1:6,
   subplot(3,2,n);
   qqplot(d(:,n)); end
Python
from scipy import stats
import matplotlib.pyplot as plt

# Uses d and names from the data-generation block above.
fig, axes = plt.subplots(3, 2, figsize=(8, 9))
for column, ax, name in zip(d.T, axes.flat, names):
    stats.probplot(column, dist='norm', plot=ax)
    ax.set_title(name)
fig.tight_layout()
plt.show()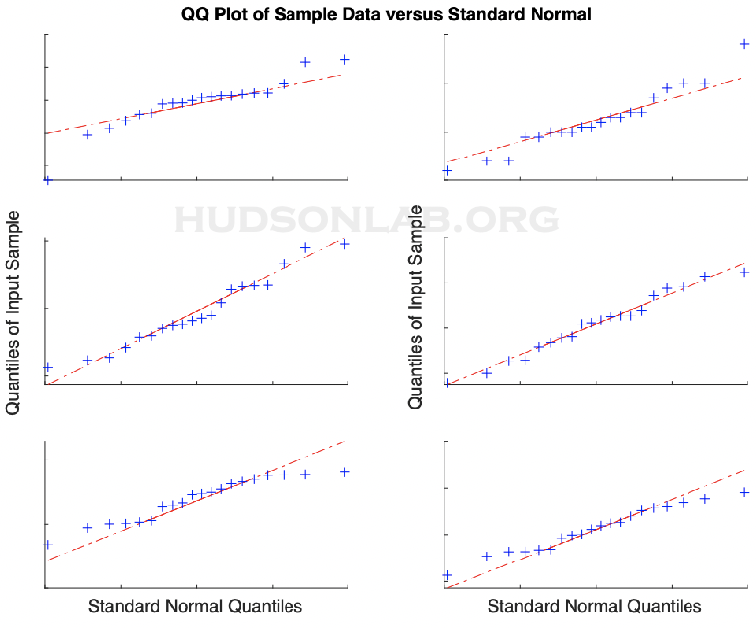
-
The graphical method is qualitative, and surprisingly difficult to interpret.
- For example, only the middle lefthand plot is drawn from a Gaussian, and yet I would say that upper 4 of the 6 plots seem to have data that fall on the straight red prediction line (and interestingly, only the upper left plot is ever flagged as non-normal by any of the statistical tests we explore below).
2) statistical method
-
If we are not particularly enamored of the graphical method of plotting q-q plots to assess normality, then one generally turns to statistical methods of testing normality.
-
Statistical tests of normality are standard statistical hypothesis tests, where your null hypothesis is that there is no difference between your data and normally distributed data
- you reject the null hypothesis if the p-value returned by the statistical test is below the -criterion level (usually ).
-
If you like having options, then you will enjoy statistical normality testing, as options abound:
- Shapiro-Wilk test - This is the statistical version of the q-q plot test we looked at above. It looks for a straight-line relation between the order statistics of the sample and those expected in a normal distribution.
- Anderson–Darling test - Compares the cumulative distribution function (cdf) of the normal distribution to the empirical cumulative distribution of the data.
- Cramér–von Mises test - As with Anderson-Darling, it compares the cdf of the normal distribution to the empirical cdf of the data.
- Kolmogorov-Smirnov test - As with the Anderson-Darling and Cramér–von Mises, it compares the normal cdf to the empirical cdf of the data.
- Lilliefors test - Variant of the KS test that attempts to take account of the fact that the mean and variance of the empirical distribution are unknown.
- D’Agostino K2 statistic - a test meant to detect deviations from the skewness and kurtosis (higher central moments of the distribution) of the empirical distribution from those values predicted by normality.
-
Note that Matlab does not have a built-in function for all of the normality tests listed here, so we use the function normailtytest.m downloaded from Matlab Central online:
MATLAB
T=nan(6); %Table of statistical p-values for normality tests
for n=1:6,
Ps=normalitytest(d(:,n)');
pSW=Ps(7,2);
[~,pAD]=adtest(d(:,n));
pCvM=Ps(6,2);
pKS=kstest((d(:,n)-mean(d(:,n)))/std(d(:,n)));
[~,pLL]=lillietest(d(:,n));
pDG=Ps(end,2);
T(n,:)=[pSW pAD pCvM pKS pLL pDG]; end
Python
import numpy as np
from scipy import stats
from statsmodels.stats.diagnostic import normal_ad, lilliefors

# Uses d and names from the data-generation block above.
# Requires NumPy, SciPy >= 1.15, and statsmodels.
mc_rng = np.random.default_rng(2)
table = np.full((d.shape[1], 6), np.nan)
for n, x in enumerate(d.T):
    p_sw = stats.shapiro(x).pvalue
    _, p_ad = normal_ad(x)
    # Composite-normal CvM test: fit mean/sd again in each bootstrap
    # sample. This is a Monte Carlo test, not normalitytest.m's formula.
    cvm = stats.goodness_of_fit(stats.norm, x, statistic='cvm',
                               n_mc_samples=4999, rng=mc_rng)
    p_cvm = cvm.pvalue
    z = (x - x.mean()) / x.std(ddof=1)
    # Reference KS p-value, uncalibrated after estimating mean/sd.
    # Use Lilliefors below for a KS normality test with estimated parameters.
    p_ks = stats.kstest(z, 'norm').pvalue
    # Table p-values are bounded: <=.001 and >=.990 are returned
    # as .001 and .990, respectively, rather than more precise values.
    _, p_ll = lilliefors(x, dist='norm', pvalmethod='table')
    p_dg = stats.normaltest(x).pvalue
    table[n] = [p_sw, p_ad, p_cvm, p_ks, p_ll, p_dg]
print('distribution       S-W     A-D   CvM(MC)  KS(ref)     L       D')
for name, row in zip(names, table):
print(f"{name:14s} " + ' '.join(f"{p:8.4f}" for p in row))| S-W | A-D | C-vM | K-S | L | D | |
|---|---|---|---|---|---|---|
| Cauchy | 0.0213 | 0.0180 | 0.0156 | 0.4185 | 0.0394 | 0.0045 |
| Poisson | 0.3933 | 0.3001 | 0.2430 | 0.7304 | 0.2384 | 0.2750 |
| Normal | 0.4839 | 0.5750 | 0.5205 | 0.8552 | 0.4092 | 0.6276 |
| Student | 0.8102 | 0.8665 | 0.8168 | 0.9789 | 0.5000 | 0.8071 |
| vonMises | 0.1302 | 0.1577 | 0.1940 | 0.8479 | 0.3957 | 0.3803 |
| Nakagami | 0.7753 | 0.7720 | 0.7952 | 0.9254 | 0.5000 | 0.7427 |
-
First, we should be glad to see that the Gaussian distribution’s sample data does not cause the null hypothesis to be rejected by any of the statistical tests.
- Only the Cauchy distribution’s sample causes the null hypothesis that the data are samples from a Gaussian distribution to be rejected (correctly), by all tests but the Kolmogorov-Smirnov test.
An important problem: Multiple ‘equivalent’ statistical tests: which do I use?
Within statistical practice you will often find that there are multiple statistical methods that can be used to test for the same thing, and it is left to you to choose one from among the list when you analyze your data.
-
One way to resolve the problem of multiple equivalent statistical tests is to try them all (creating something similar to the table of p-values above)
- However, this is a situation that encourages scientists to engage in the ethically dubious practice of ‘p-hacking’, wherein one tries multiple equivalent statistical tests and reports only one test: that which yields the most desirable result.
-
It is much better to look at the details of the differences among the various seemingly equivalent tests and determine which of the test’s details makes the most sense in your particular situation.
- At the very least, you must decide what test (or combination of tests) will determine your inference regarding normality before you see the results of the test(s).
Are there errors in the logical foundations of normality testing?
-
In most cases, we would prefer to use parametric statistical testing for our data.
-
This means normality testing puts us in a situation where we are better off (i.e., we will be using a more powerful statistical test) if we do not reject the null hypothesis.
-
This is, however, explicitly not how you are supposed to construct hypothesis tests.
-
Your null hypothesis is supposed to be a plausible hypothesis that you nevertheless are attempting to reject.
-
Here, we typically are in a different position, where we have no reason to believe that the data are non-normal, and we hope NOT to reject the null hypothesis
- i.e., we do NOT wish to conclude the data were drawn from a non-normal distribution
-
-
-
How does this reversal of our usual attitude toward the null hypothesis affect the the logic of the p-value in this hypothesis test?
-
Recall the logic of the p-value and the hypothesis test is:
- you reject the null hypothesis when the p-value is small, because you have observed a dataset that is lower-frequency than the alpha-criterion that defines the edge of the region in the distribution’s tails that contains 5% of the distribution’s probability mass.
-
That logic is very often blatantly violated during normality testing:
-
In normality testing you are usually attempting to justify your use of parametric statistical methods
- you do so by showing that the test ‘fails to reject’ the null hypothesis that your data are drawn from a Gaussian.
-
-
The opportunity for p-hacking described above points generally to a logical error that seems to be present in normality testing. Logically, if you have two equivalent tests of the same hypothesis (i.e., two or more tests of normality), then they must be mathematically equivalent. If they are not mathematically equivalent, they cannot have been equivalent tests of the same hypothesis.
- Although this might tend to make us cautious about the entire enterprise, the next section should make us avoid normality testing entirely.
-
In other words, you are inferring that you do indeed have normally distributed data when your p-value is above the -criterion (i.e., when ).
-
This type of inference is strictly forbidden by the logic of null hypothesis testing:
-
You only find evidence against hypotheses within classical statistics, never in favor of hypotheses (only Bayesian analysis allows evidence favoring hypotheses)
-
‘Failing to reject the null hypothesis’ is explicitly not the same as ‘accepting the null hypothesis’.
-
Indeed the logic of null hypothesis testing is very clear on this point:
-
You can never accept the null hypothesis within classical statistics
-
A failure to reject the null hypothesis can only be interpreted as an inability to make any inference about the distribution whatsoever
-
-
-
To truly understand the logical error inherent in normality testing, let’s take a step back from normality testing specifically, and consider the general topic of statistical testing for any probability distribution (Gaussian, Poisson, binomial, or whatever):
- In a statistical test of this kind, you can only:
-
[p < criterion] reject the hypothesis that the probability distribution under consideration is the ‘correct’ sampling distribution to describe your data sample
-
[p > criterion] fail to reject, and therefore make no conclusion regarding whether the sampling distribution being tested is the ‘correct’ sampling distribution to describe your experimental data sample
-
In other words, you can never find evidence that allows you to conclude that your experimental data sample comes from a particular sampling distribution
-
thus, anyone who requires that a probability distribution be ‘verified’ via statistical testing is essentially precluded from even beginning a classical statistical data analysis, since:
-
you can never ‘verify’ any hypothesis regarding the sampling distribution using classical statistics
- i.e., you can only reject, never verify your hypothesis
-